Posts

An Introduction to Text Analytics

Image
Text analytics, sometimes alternately referred to as text data mining or  text mining , refers to the process of deriving high-quality information from text .  High-quality information is typically derived through the devising of patterns and trends through means such as statistical pattern learning .  Text mining usually involves the process of structuring the input text , deriving patterns within the structured data , and finally evaluation and interpretation of the output.   Typical text mining tasks include text categorization , text clustering , concept / entity extraction , production of granular taxonomies,  sentiment analysis , document summarization  and entity relation modeling (i.e., learning relations between named entities ).   The overarching goal is, essentially, to turn text into data for analysis via application of natural language processing (NLP) and analytical methods.   A typical application is to scan a set of documents wr...

Using decision trees in evidence based medicine

Image
In today's post, we explore the use of decision trees in evidence based medicine.   In 1996  David Sackett  wrote that "Evidence-based medicine is the conscientious, explicit and judicious use of current best evidence in making decisions about the care of individual patients" [Source: Wikipedia]. For our analysis, we start with a data set which contains data about a number of patients all of whom suffered from the same illness.  Each of these patients responded well to one of five medications.  We will use a decision tree to understand what factors in each patients history led to them responding well to one specific medication over the others.  We will then use our findings to generate a set of evidence based rules or policies that can be followed by doctors to treat this illness in future patients.  As part of our analysis, we will also explore how to interpret decision trees. Let us first look at our data set: As can be seen, the da...

Numeric Measures for Association Rules

Image
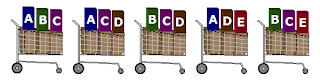
In today's post, we dive into understanding Association Rules for Market Basket Analysis and discuss three numeric measures that should be considered before deciding to act on / make a business decision based on associations that have been observed in the data: (1) Support (2) Confidence and (3) Lift. Association rules are typically written in the format: Left hand side Implies Right hand side The left hand side is referred to as the Antecedent and the right hand side is the Consequent.  The Antecedent means a thing that logically precedes another while a Consequent means a thing that follows as a result.  For example, in the association rule: {Butter, Eggs} Implies {Bread} Butter and eggs are the Antecedent while Bread is the Consequent.  What this rule means that if you were to pick a shopping cart at random and find butter and eggs in there, there is a chance that you are also likely to find bread. The numeric measures mentioned above (Support, Confidenc...

Market Basket Analysis

Image
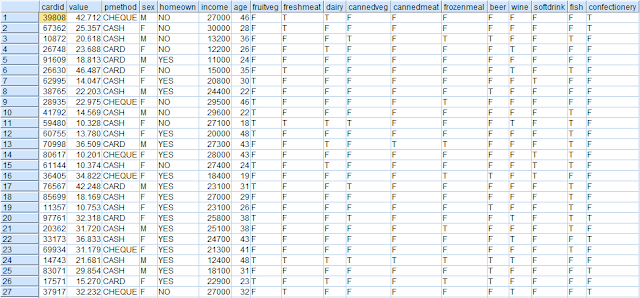
Affinity analysis is a data analysis and data mining technique that discovers co-occurrence relationships among activities performed by (or recorded about) specific individuals or groups. In general, this can be applied to any process where agents can be uniquely identified and information about their activities can be recorded. In retail, affinity analysis is used to perform market basket analysis, in which retailers seek to understand the purchase behavior of customers. This information can then be used for purposes of cross-selling and up-selling, in addition to influencing sales promotions, loyalty programs, store design, and discount plans [Source: Wikipedia]. In today's post, we use fictitious data from a supermarket describing items bought together by a set a individuals along with personal data that can be acquired through a loyalty scheme.  We will use SPSS Modeler to identify relationships between items bought together so we can understand which items are typically...

Predicting Telco Churn using Binomial Logistic Regression

Image
In today's post, we will use a sample data set from a fictitious telecommunications company with the objective of predicting customer churn.  Churn refers to the loss of customers to another company.    A large percentage of subscribers signing up with a new wireless carrier every year are coming from another wireless provider and hence are already churners.  It costs hundreds of dollars to acquire a new customer in most Telecom industries.  So when a customer leaves, the company loses not only the future revenue from this customer but also the resources spent on customer acquisition in the first place. Given this background, having the ability to predict potential churners before they churn and making them an offer that would get them to stay is an extremely valuable proposition.  Let us see how we can do this using a Binomial Logistic Regression model in SPSS Modeler. To start with, we take our sample data set from a fictitious telco.  The ...